What if a $399 edge device could simultaneously index millions of technical documents, search video frames and audio logs in under 15 milliseconds, execute an 8B-class local language model, and maintain a deterministic real-time control loop—all offline? Moorcheh.ai put this question to the test by profiling a complete multimodal agentic memory pipeline on the Arduino VENTUNO Q board.
The challenge facing physical AI at the edge differs sharply from cloud deployments. Every megabyte allocated to vector databases, graph structures, and transaction logs represents memory unavailable for Vision-Language Models, KV caches, speech processing, and live vision buffers. On hardware with finite RAM, the traditional approach to vector retrieval hits a hard wall.
The hardware foundation: Dual-brain architecture
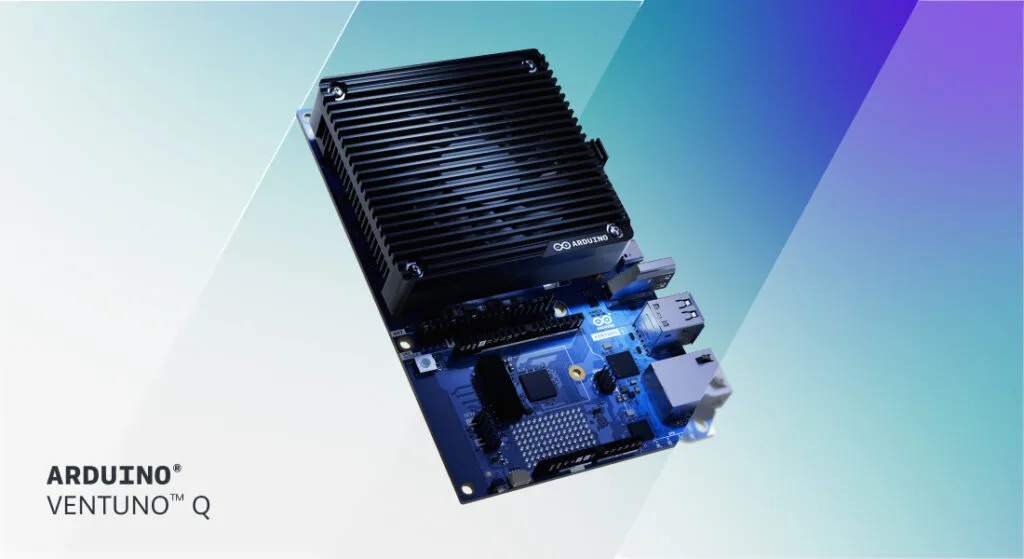
The VENTUNO Q pairs two distinct compute engines. A Qualcomm Dragonwing IQ-8275 processor handles Linux and AI workloads, featuring an 8-core Qualcomm Kryo CPU, Qualcomm Adreno GPU, and a Qualcomm Hexagon NPU capable of delivering up to 40 dense TOPS, backed by 16 GB of LPDDR5 system RAM. An STM32H5 microcontroller manages real-time control, enabling sub-millisecond motor and sensor loops.
While 16 GB represents substantial capacity for an edge device, conventional vector retrieval systems quickly exhaust available memory when scaling to production workloads.
The memory wall in multimodal retrieval
Robotics and smart edge systems ingest vectors from heterogeneous sources: text documentation, PDF schematics, camera keyframes, video segments, and audio recordings. When storing high-dimensional embeddings using standard Approximate Nearest Neighbor methods like HNSW, the costs escalate rapidly:
- Uncompressed float32 vectors demand 6.14 KB per entry
- Graph adjacency lists, pointer structures, and write-ahead logs expand dramatically; at one million vectors, HNSW consumes 7.4 GB of RAM and 13.2 GiB on disk
- Ingesting new vectors requires continuous graph construction that can occupy the board for hours
On a device with 15.2 GB of usable RAM, dedicating 7.4 GB to the vector database triggers Out-Of-Memory crashes the moment a quantized language model, vision processing, or speech engines load alongside it.
The approach: Information binarization and agentic memory
Moorcheh addresses this constraint through information binarization, compressing high-dimensional vectors to a single bit per dimension. A 1,536-dimension embedding shrinks to just 192 bytes. Retrieval executes as a direct bit scan on the Kryo CPU with integrated shortlist reranking, leaving the Hexagon NPU and approximately 14.5 GB of system RAM untouched for neural inference.
Layered above the search engine sits Memanto, Moorcheh's open-source agentic memory system. Memanto supersedes outdated information, removes stale observations, and assembles structured context summaries before prompts reach the local LLM.
Benchmarks on physical hardware
Rather than relying on workstation simulations, Moorcheh was tested directly on VENTUNO Q hardware against standard HNSW indexes across 10,000, 100,000, and 1,000,000-vector datasets:
- Zero index-build latency: Moorcheh requires 0 seconds of graph construction after upload, while HNSW needed 2 hours and 58 minutes to build its graph for 1M vectors on the board
- Sub-gigabyte footprint: At 1,000,000 items, Moorcheh's retrieval occupies 737 MB of RAM and 294 MiB on disk, compared to 7.4 GB RAM and 13.2 GiB disk for HNSW
- Predictable latency: Moorcheh delivered 14.84 ms median query latency at 1M items, with candidate reranking completed within that window
Building a complete multimodal stack
Because Moorcheh's retrieval process leaves over 14.5 GB of RAM available, developers can deploy an entire multimodal AI stack on a single VENTUNO Q:
- Retrieval engine: Moorcheh (737 MB RAM / 294 MiB disk)
- Embedding model: BGE-small (~676 MB resident)
- Local language model: Qwen 2.5 3B or 7B Q4 (~2.1 GB to ~4.7 GB via Qualcomm GenieX)
- Speech-to-text: Whisper small (~750 MB resident)
- Text-to-speech: Piper (~470 MB resident)
- Object detection: YOLOv8n 1080p stream (~300 MB)
This concurrent stack consumes between 5.0 GB and 7.6 GB, preserving substantial headroom for KV-cache expansion, operating system buffers, and ROS 2 communication nodes.
Real-world applications
Air-gapped retail voice and vision kiosks
Retail kiosks running on the VENTUNO Q operate entirely offline without cloud APIs or store Wi-Fi. When a customer asks "Where can I find the replacement filter for this model, and how do I install it?", Whisper transcribes the voice query while Moorcheh searches across 1,000,000 multimodal catalog entries, PDF schematics, and instructional video timestamps in approximately 15 ms. The local LLM generates grounded step-by-step guidance, and Piper speaks the answer while the screen displays the exact diagram retrieved by Moorcheh.
Autonomous mobile robots with spatial video memory
Mobile robots navigating dynamic warehouses, hospital corridors, and retail floors use the VENTUNO Q as an integrated compute brain. Rather than sending millions of video feeds to a cloud server, the robot's vision pipeline embeds live keyframes, depth maps, and obstacle logs directly into Moorcheh. Moorcheh functions as the robot's resident episodic memory on the VENTUNO Q. When a pallet goes missing or a corridor becomes obstructed, the robot queries Moorcheh to recall exactly when, where, and in which video frame the asset was last observed visually, without leaving the edge.
Hands-free field assist across millions of schematics and video
Field technicians servicing aerospace hardware, industrial turbines, or off-grid telecom towers carry rugged inspection kits powered by the VENTUNO Q. The board hosts a complete on-device technical library of over one million engineering schematics, wiring diagrams, diagnostic guides, and maintenance video clips indexed entirely within Moorcheh. When a technician points a live camera at a broken component and asks a spoken diagnostic question, the VENTUNO Q captures both video frames and audio simultaneously. Moorcheh performs a cross-modal vector search across the entire library in under 15 ms, retrieving the matching wiring diagram and video snippet for the local LLM to narrate through the technician's headset.
Source: Arduino Blog